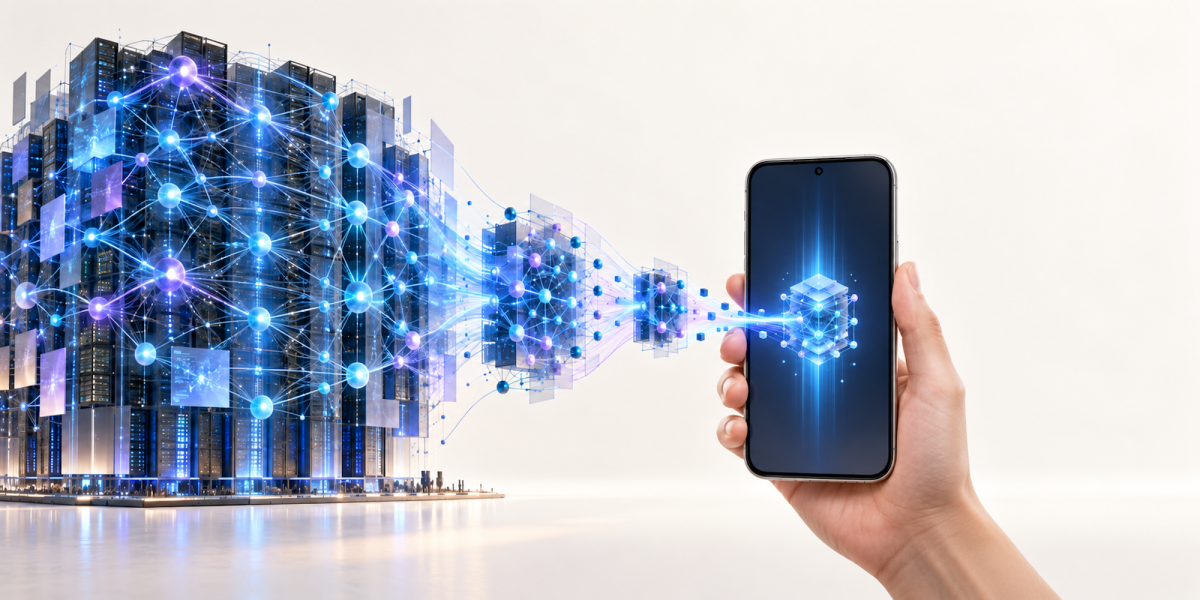
Тус стартап нь том хэлний загваруудыг (LLM) гүйцэтгэл алдагдуулахгүйгээр ухаалаг утас болон хувийн компьютерт суулгах боломжтой болгож байна.
Калифорнийн Технологийн Институтийн (Caltech) судлаачдын үүсгэн байгуулсан PrismML стартап нь хиймэл оюун ухааны загваруудын хэмжээг эрс багасгах шинэ технологийг хөгжүүлж байна. Тус компани саяхан “Bonsai 2 27B” загвараа танилцуулсан бөгөөд энэ нь Alibaba-ийн Qwen3.8 27B нээлттэй эх сурвалжтай загварыг 5.9 ГБ хүртэл шахаж, санах ойн ашиглалтыг 9-10 дахин бууруулжээ.
Энэхүү шийдэл нь загварын жин буюу мэдээлэл хадгалах хэсгийг 16 битийн оронд “ternary” буюу +1, -1, 0 гэсэн гурван утгаар илэрхийлэх зарчимд суурилдаг. Гүйцэтгэлийн хувьд уг загвар нь эх хувилбарынхаа 98 хувьтай тэнцэхүйц үр дүнг үзүүлж байгаа нь өмнөх хувилбарын 95 хувиас ахисан үзүүлэлт юм.
Компанийн гүйцэтгэх захирал Бабак Хассибигийн мэдээлснээр, тэдний дараагийн зорилго нь хэдэн зуун тэрбум параметртэй илүү том загваруудыг ижил аргаар шахах юм. Энэ нь загварын хэмжээ том байх тусам чанарыг алдагдуулахгүйгээр шахах боломж илүү нээлттэй байдагтай холбоотой аж.
Тус стартап нь 22.25 сая долларын үрийн санхүүжилт татсан бөгөөд Khosla Ventures, Cerberus Capital, Caltech зэрэг хөрөнгө оруулагчдаар дэмжигддэг. Зөвлөхөөр нь Databricks-ийг үндэслэгчдийн нэг Ион Стойка ажилладаг бөгөөд тэрээр энэхүү технологи нь хиймэл оюун ухааныг үүлэн тооцооллоос хамааралгүйгээр, хувийн нууцлалыг хадгалан хэрэглэгчийн төхөөрөмж дээр шууд ажиллуулах боломжийг бүрдүүлнэ гэж үзэж байна.
Дэлгэрэнгүйг эх сурвалжаас харах
↓Эх сурвалжийг нээх ↓
If AI lab PrismML isn’t on your radar yet, it should be — not because it’s raised gobs of money (it hasn’t yet, just a $22.25 million seed round), but because of the technical minds involved and the potentially industry-changing tech it’s developing.
PrismML is betting that capable, high-performing, reasoning large language models don’t, in fact, have to be large.
It is making reasoning models so small they can fit on PCs and smartphones. (It’s even rumored to be in talks with Apple, though CEO Babak Hassibi declined to comment on that to TechCrunch.)
On Thursday, PrismML released Bonsai 2 27B, its latest in a family of models, which compresses Qwen3.8 27B, a widely used open-source model from Alibaba, down to 5.9 GB. That’s small enough to fit on a PC and, possibly, a high-end smartphone. It’s a 9x to 10x reduction in memory versus the original.
PrismML was founded by a group of Caltech researchers and is led by Hassibi, a Caltech professor and an expert in compression technologies. The startup also counts Ion Stoica as an advisor. Stoica is a co-founder of Databricks (and other companies) and the director of Berkeley’s famed Sky Computing Lab, which has birthed many technologies and startups, from Letta to SGLang.
PrismML is also backed by investors Khosla Ventures, Cerberus Capital, and Caltech.
This startup is certainly not the only company working on LLM compression tech. Multiverse Computing, founded by a well-known professor from Spain’s Donostia International Physics Center, is another. (And Multiverse Computing has raised gobs of cash.)
But Hassibi says that PrismML’s compression tech is unique because its LLMs have lost virtually no performance compared with the originals. Bonsai 2 matches 98% of Qwen’s aggregate benchmark scores. That’s up from the first Bonsai, released a couple of months ago in March, that matched 95%. That original model has already been downloaded over 11 million times, and PrismML’s even smaller models have been downloaded another 2.6 million times, the company says.
So this shows that PrismML’s compression results have improved from one release to the next. Whether it could ever get to 100% benchmark performance parity is a question that remains to be seen. Compression will likely always have some impact, Hassibi says.
Still, perfect benchmark parity is fairly academic anyway. LLMs are not so accurate in their uncompressed form, and benchmarks not so perfectly reflective of actual tasks, that a 2% degradation would likely meaningfully affect how a model performs in actual use. (Plus, the surrounding software — the harness a model runs inside of — matters a lot when it comes to accuracy, too.)
PrismML says it achieves this by shrinking the “weights” that make up a model — weights are, essentially, the information a model learns and stores during training. Normally, each weight requires 16 bits. PrismML’s approach, called “ternary” weights, simplifies that down to three: +1, −1, or 0. With far smaller values to store for each weight, the model takes up dramatically less space. (For a deeper dive on the compression technique, here’s the project’s GitHub page.)
The startup’s next goal is to apply this compression technique to even bigger models. “The next models that we will release, hopefully in the next couple of months, will be in the several-hundred-billion-parameter range, and I expect it will be easier to retain the intelligence there,” Hassibi told TechCrunch.
As model size grows, he added, “There is more room to be able to compress them without losing the intelligence. So I would just say, as a general trend, for larger models, it’s easier to get to 100%.”
Stoica tells us that he’s excited for this tech because it’s making it possible for advanced models to run on users’ devices. “You are going to have intelligence at your fingertips, and it’s going to be free because it’s going to run on the device you already bought. It’s also going to be private, because you’re not going to send it to the cloud.”
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.